Blog

Tampilan Layout:
What Is PageIndex? How to Build a Vectorless RAG System (No Embeddings, No Vector DB)
Admin 08 Apr 2026 843
What Is PageIndex? How to Build a Vectorless RAG System (No Embeddings, No Vector DB)

PageIndex is a vectorless, reasoning-based Retrieval-Augmented Generation (RAG) approach that retrieves answers from long documents without using embe...
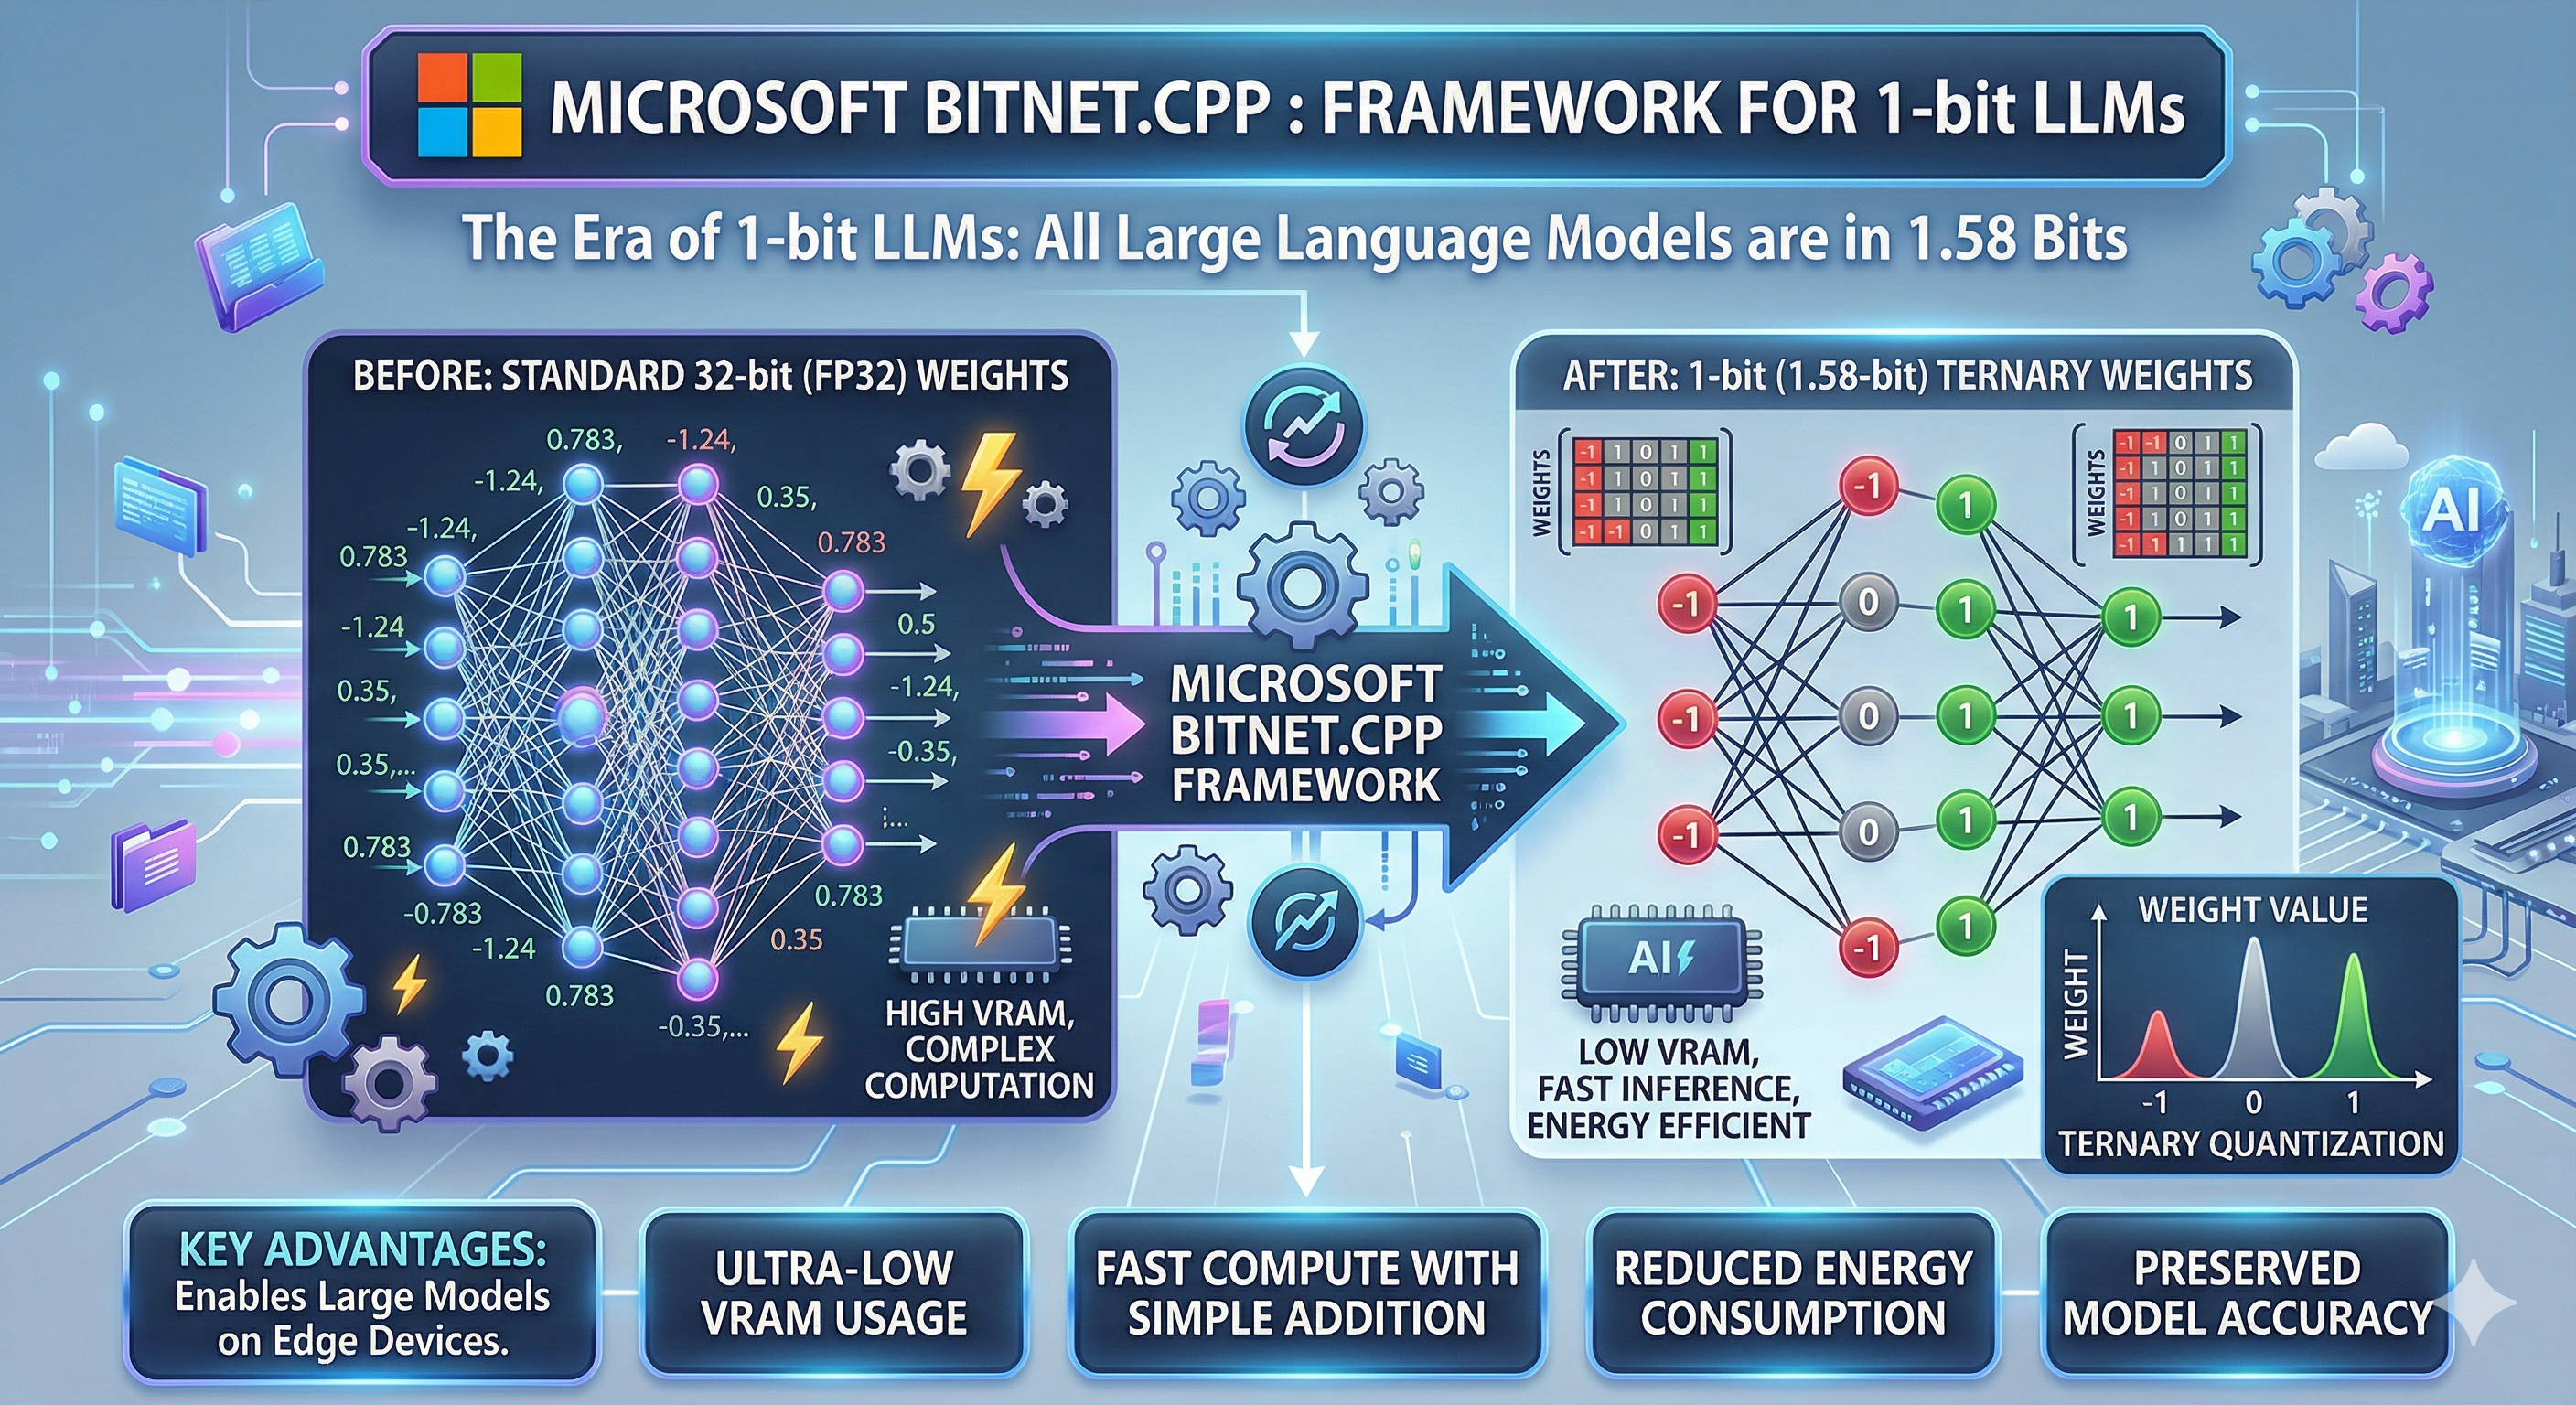
Microsoft BitNet.cpp : Framework for 1-bit LLMs
Admin 07 Apr 2026 308
Microsoft BitNet.cpp : Framework for 1-bit LLMs

As Generative AI continues to push boundaries, one of the biggest challenges facing researchers and developers is the sheer size and complexity of LLM...

SmolLM3 : The best small LLM for everything
Admin 02 Apr 2026 242
SmolLM3 : The best small LLM for everything

So, Hugging Face just dropped SmolLM3. And no, the name isn’t ironic. It’s a 3-billion parameter model, but it behaves like it’s twice that beating mo...

Fine Tune Large Language Model (LLM) on a Custom Dataset with QLoRA
Admin 01 Apr 2026 138
Fine Tune Large Language Model (LLM) on a Custom Dataset with QLoRA

The field of natural language processing has been revolutionized by large language models (LLMs), which showcase advanced capabilities and sophisticat...

The Comprehensive Guide to Fine-tuning LLM
Admin 30 Mar 2026 235
The Comprehensive Guide to Fine-tuning LLM

Fine-tuning is the process of taking a pre-trained language model (a large neural network that has learned general language patterns from a massive da...

RAG Architecture — Building AI Apps That Know Your Data
Admin 27 Mar 2026 138
RAG Architecture — Building AI Apps That Know Your Data

Perplexity AI processes 100M+ queries per month. GitHub Copilot references your entire codebase to suggest context-aware code. Both are powered by...

Retrieval-Augmented Generation (RAG) from basics to advanced
Admin 26 Mar 2026 152
Retrieval-Augmented Generation (RAG) from basics to advanced

Retrieval-Augmented Generation (RAG) is a technique that enhances language model generation by incorporating external knowledge....

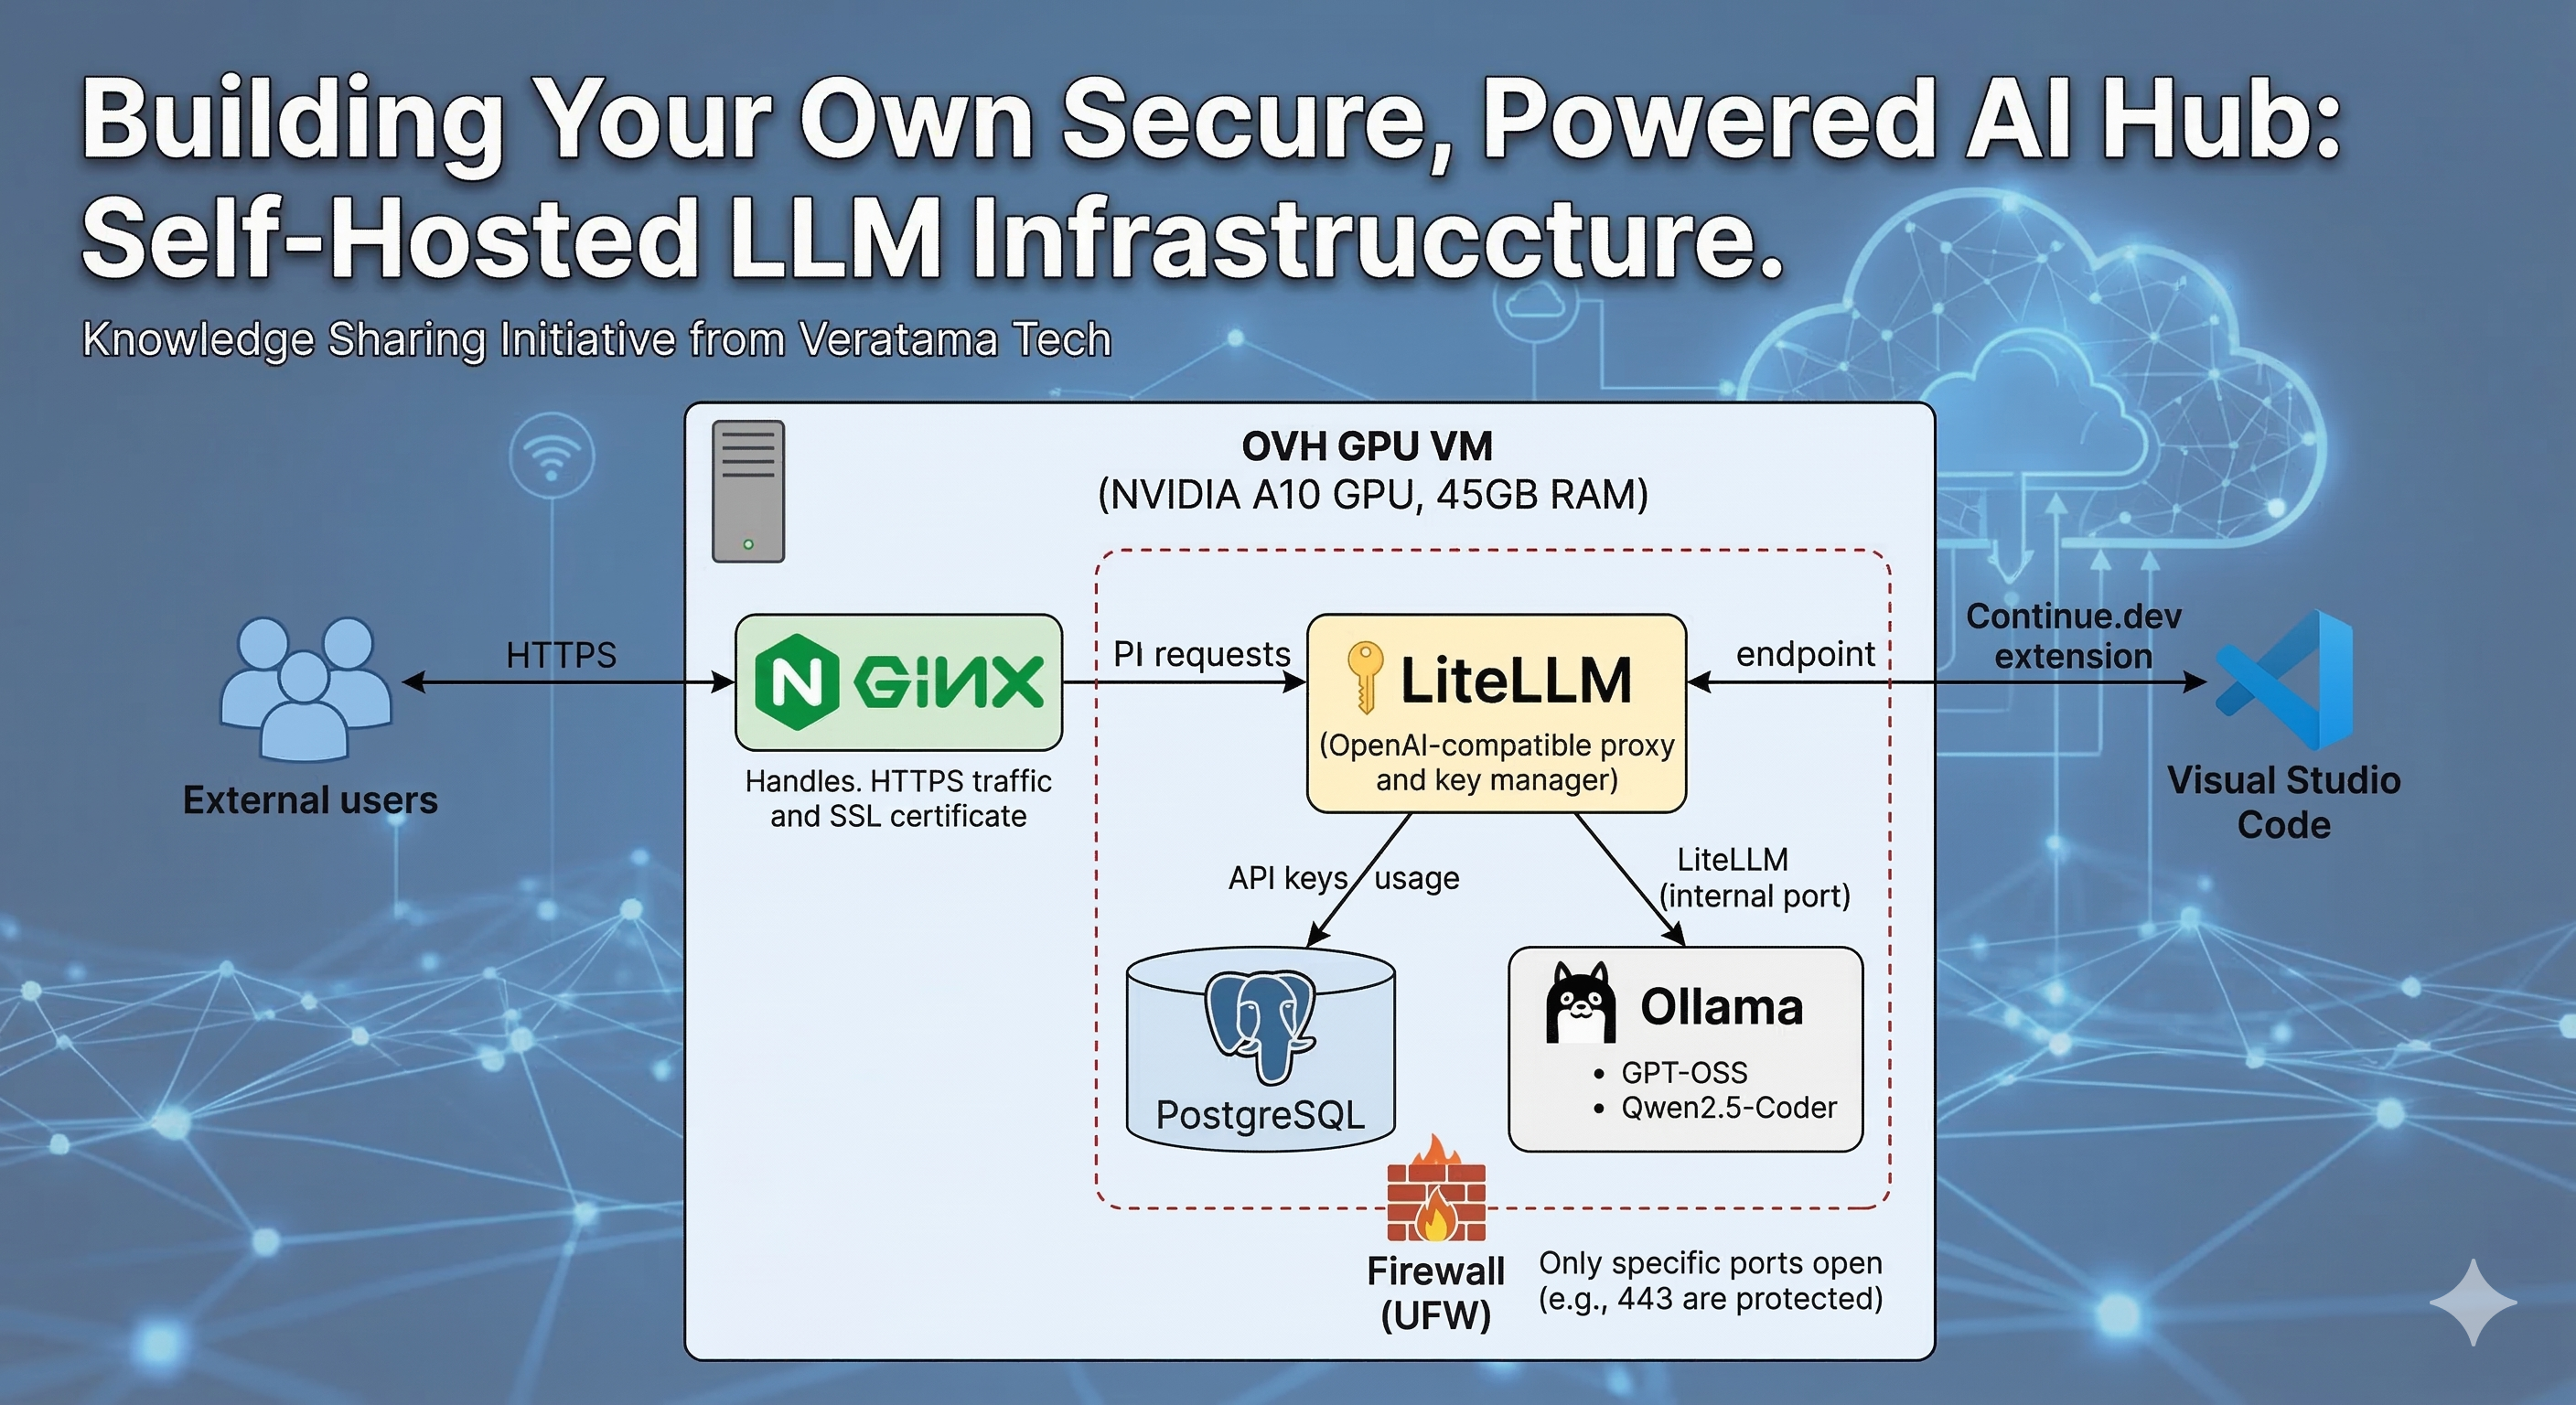
Complete Self-Hosted LLM Setup: Ollama + LiteLLM + Continue.dev Integration Guide
Admin 12 Feb 2026 869
Complete Self-Hosted LLM Setup: Ollama + LiteLLM + Continue.dev Integration Guide

This guide was born from that idea: build a personal host for Large Language Models (LLMs) from scratch. For our experiment, we chose an...

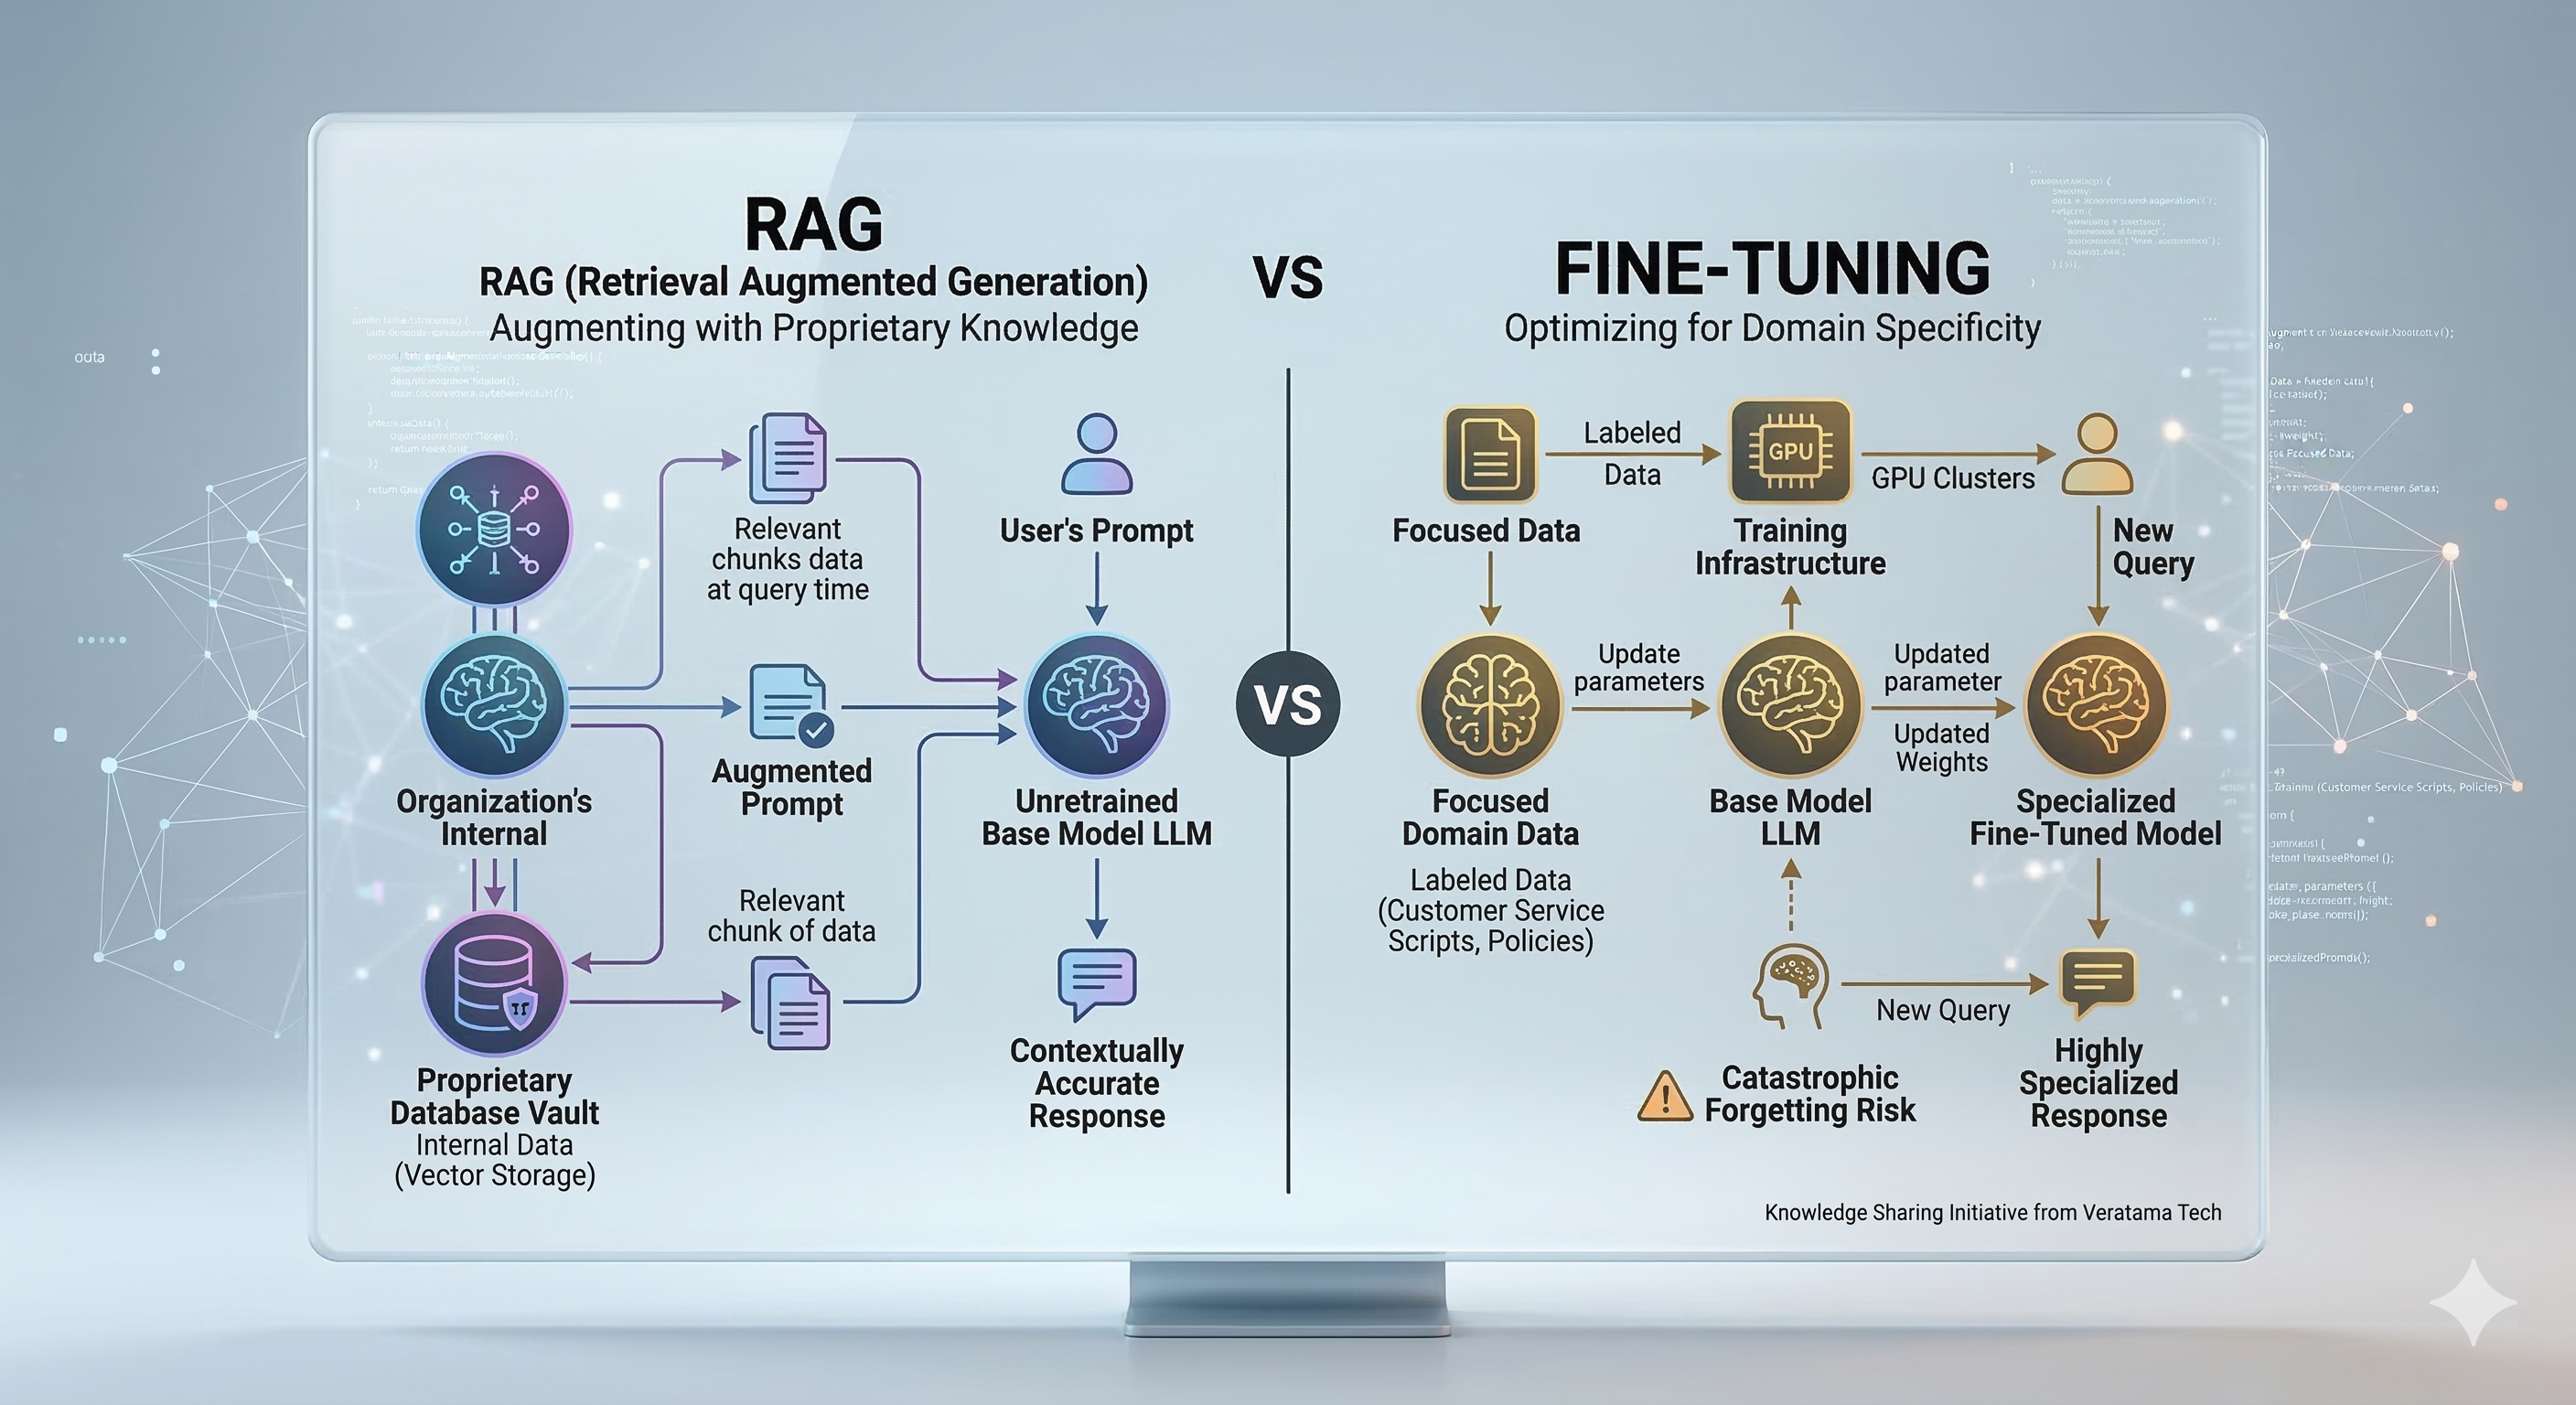
RAG vs. fine-tuning
Admin 12 Feb 2026 275
RAG vs. fine-tuning

Retrieval augmented generation (RAG) and fine-tuning are two methods enterprises can use to get more value out of large language models (LLMs)...